How to Post-Train Text-to-Image Models: Combining Preference and Rubric Rewards
How do we post-train a text-to-image model? While recent advances have made reinforcement learning increasingly practical for diffusion-based models, improving frontier open-source models remains surprisingly difficult. The key question is: what reward should we optimize?
Human preference is an obvious starting point. If people consistently prefer one image over another, a reward model trained on those choices can provide a powerful learning signal. But preference alone does not capture everything users care about: an image can look great while missing an object from the prompt, adding things that were never requested, or drifting away from the requested style.
In our latest work, we explore a simple idea: combine human preference with explicit rubric-based rewards. We train an Arena reward model on roughly 5 million pairwise human preference votes, and use vision-language models to automatically construct rubrics that evaluate whether an image follows the prompt, respects relevant constraints, and avoids known reward-hacking behaviors.
The result is a post-training recipe that improves two already-strong text-to-image models under live human evaluation. Our post-trained FLUX.2-dev gains 69 Arena points in our live T2I leaderboard, while our post-trained Ideogram 4 reaches 1224 Arena score and surpasses every publicly listed open-source model by September 4, 2026.
Live Arena Results
We evaluate post-trained models through live, blind, pairwise human comparisons on the Text-to-Image Arena leaderboard. FLUX.2-dev improves from 1132.8 to 1202 Arena score after post-training, and Ideogram 4 improves from 1204 to 1224.

Reward Design for T2I Post-Training
Recent methods such as Flow-GRPO and DiffusionNFT have made reinforcement learning increasingly practical for diffusion- and flow-based image generation models. But what reward actually represents a better image?
Learning human preference from pairwise comparisons
Our first component is a reward model trained on real-world human preferences. Using roughly 5 million pairwise human votes collected from Text-to-Image Arena across more than 100 models, we train a Bradley—Terry reward model. Given a prompt and an image, the model outputs a scalar preference score that captures broad human judgments such as visual quality, composition, and aesthetics. Scaling preference data matters: downstream post-training performance improves as the reward model is trained on more preference data.

Faithfulness reward through auto-rubrics
Large-scale preference data provides a strong and general signal, but it does not explicitly check whether every detail in the prompt has been correctly followed. To explicitly measure prompt following, we introduce a faithfulness reward based on automatically generated, prompt-specific rubrics.
For each training prompt, we use a language model to decompose the prompt into a tree-structured checklist of concrete yes/no questions. Each question evaluates one aspect of the requested image, such as whether an object is present, whether it has the correct attribute, whether two objects have the requested spatial relationship, or whether a specified style is preserved. Dependencies between questions are also captured: checking the color of an object only makes sense if that object is present.
A vision-language model then evaluates the generated image against these questions, and the fraction of satisfied criteria becomes the faithfulness reward. More details can be found in [1].
Other rubric rewards and ensembling
Faithfulness auto-rubric methods can construct questions that check basic object presence, attributes, and relationships. However, they are less suited to checking constraints, such as whether the user wants to avoid an undesired style, especially when these constraints are implicit. More importantly, these auto-rubrics are derived from the prompt before training and therefore cannot anticipate reward-hacking behaviors that emerge during RL training.
To complement this, we introduce rubric-based rewards for constraint satisfaction and reward-hacking prevention. The constraint reward checks whether the model introduces content that conflicts with the user’s intent, such as adding unnecessary objects, changing a requested style, or violating negative instructions. Because some prompts are open-ended and allow creative freedom, we apply this reward only when the prompt calls for relatively strict adherence.
We also use rubric-based rewards for recurring reward-hacking behaviors that emerge during RL, such as adding garbled text or drifting toward photorealism when a non-photographic style is requested.
Rather than treating these anti-reward-hack rewards as independent reward objectives, we use them to shape the preference reward through a simple gating function. Let denote the normalized preference reward and let indicate whether a reward-hacking behavior is detected:
Thus, the preference reward is preserved when no reward-hacking behavior is detected, while positive preference reward is canceled when the anti-reward-hacking signal is flagged. This allows the detector to suppress known exploits without introducing another independent objective that the policy can optimize or game.
Finally, we found that models trained with different reward configurations often develop complementary strengths. We therefore ensemble independently optimized policies directly in weight space by averaging their weight updates [2]. Together with independent reward normalization and prompt-dependent gating, this gives us a simple reward-composition recipe that works consistently without extensive reward-weight tuning.
Preventing Reward-Hacking Modes
The following examples compare images generated with and without the anti-reward-hack reward. We observe a photorealistic hacking mode during training: the model can make a result look like a realistic photograph even when the prompt asks for a non-photographic style. The anti-reward-hack gate suppresses this shortcut while retaining the gains from preference and rubric rewards.
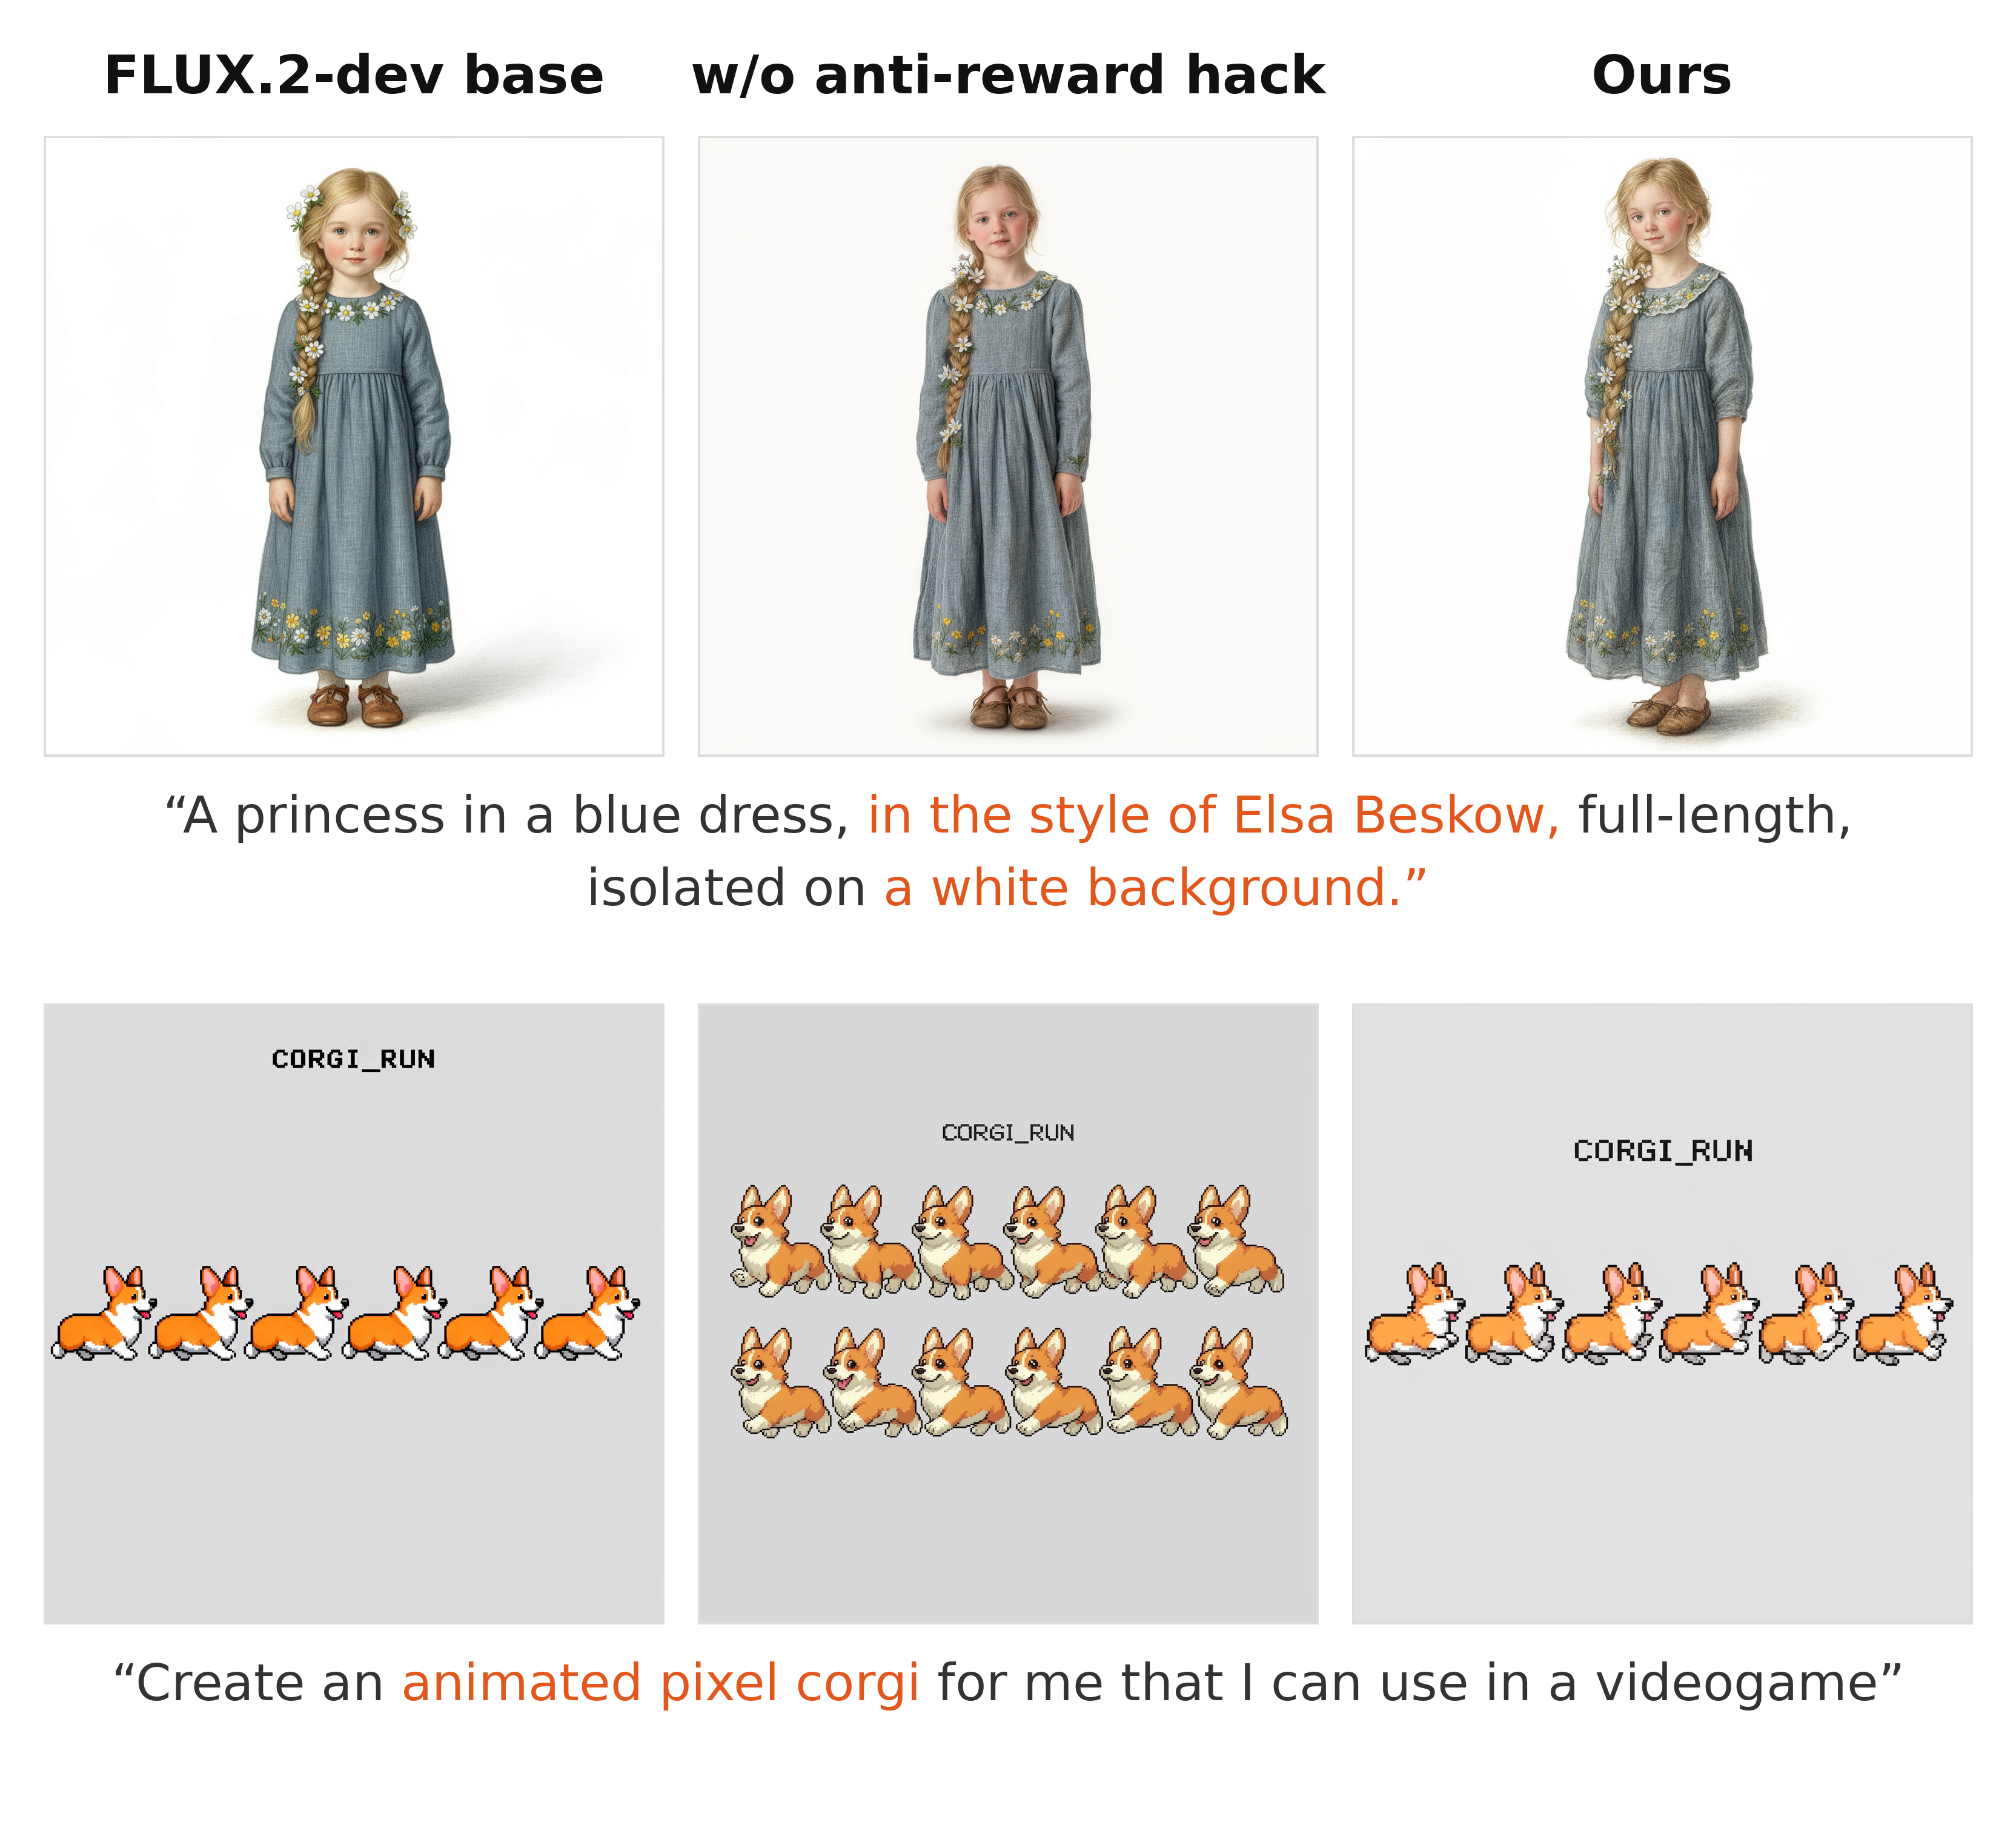
Anti-reward-hack examples on the girl and pixel-art prompts. Columns show the base model, a model without anti-reward-hack gating, and the final model.
Qualitative Examples
The following visual examples compare images generated before and after post-training. The naive approach uses only the Arena preference and faithfulness checklist rewards, while Ours uses the full recipe, adding the constraint reward, anti-reward-hack reward, and weight ensembling. The naive approach often improves prompt following but can still violate constraints or clutter the scene. The full recipe better balances visual quality with the user’s requested content and style.
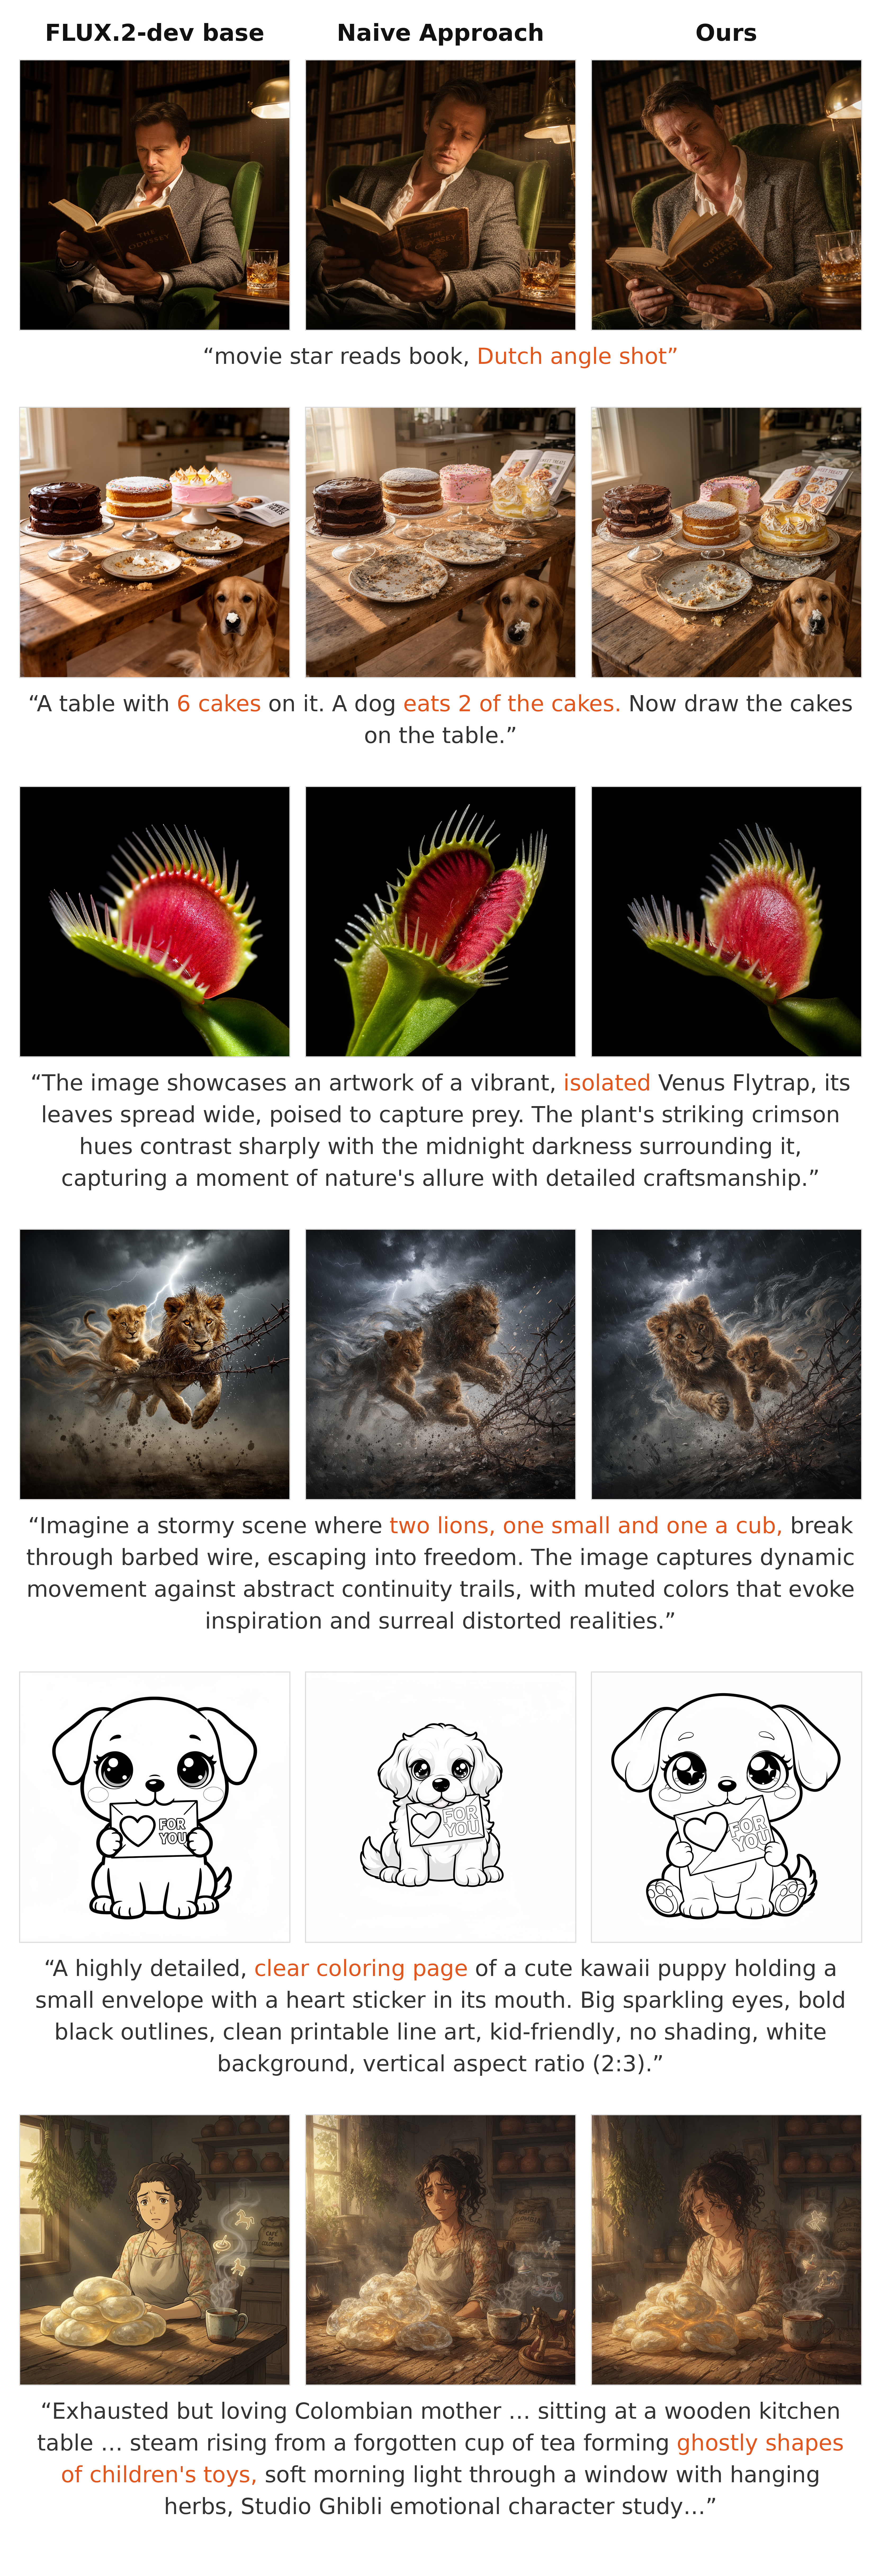
Base vs. naive preference-plus-faithfulness training vs. the full composed reward recipe.
Offline Results: Why Reward Composition Matters
We train on 10K real user prompts sampled from Arena and evaluate on a held-out set of 1K Arena prompts. For each checkpoint, we compare the post-trained model against the frozen base model using the MMRBv2 pairwise evaluation protocol, with Gemini-3.5-Flash as the judge. Each image pair is evaluated in both presentation orders to reduce position bias, and we report the resulting win rate against the base model.
| Method | Arena RM | PickScore |
|---|---|---|
| DiffusionNFT baseline | 0.290 | 0.290 |
| Faithfulness only | 0.366 | 0.366 |
| Arena-T2I-Hard | 0.589 | 0.577 |
| Preference only | 0.507 | 0.461 |
| Stage 1: preference + faithfulness + constraint | 0.642 | 0.581 |
| Stage 2: + anti-hack veto | 0.635 | 0.571 |
| Stage 3: weight-space soup | 0.660 | 0.626 |
The results show a clear progression. Optimizing preference alone is not sufficient; adding the faithfulness reward substantially improves performance, introducing the intent-gated constraint reward further raises the win rate to 64.2%, and ensembling policies trained with complementary reward configurations gives the strongest result, reaching 66.0% win rate with Arena RM. The same recipe also holds when using an open-source reward model such as PickScore.
References
[1] Ban, Y., Xie, T., An, S., Hong, Y., Frick, E., Hsu, I., et al. Arena-T2I Hard: Benchmarking and Improving Faithfulness with Dependency-Aware Checklist. NeurIPS 2026 Spotlight.
[2] Wortsman, M., Ilharco, G., Gadre, S. Y., Roelofs, R., Gontijo-Lopes, R., Morcos, A. S., et al. Model soups: averaging weights of multiple fine-tuned models improves accuracy without increasing inference time. ICML 2022.
BibTeX
@article{ban2026posttrainingt2i, title = {Post-Training Frontier Text-to-Image Models by Composing Preference and Rubric Rewards}, author = {Ban, Yuanhao and Hsu, I-Hung and Angelopoulos, Anastasios and Chiang, Wei-Lin and Stoica, Ion and Hsieh, Cho-Jui}, year = {2026}, url = {https://banyuanhao.github.io/Post-Training-Frontier-Text-to-Image-Models-by-Composing-Preference-and-Rubric-Rewards/},}